Reproducible scoring evidence · MIT + CC BY 4.0
Validate the ranking before routing leads
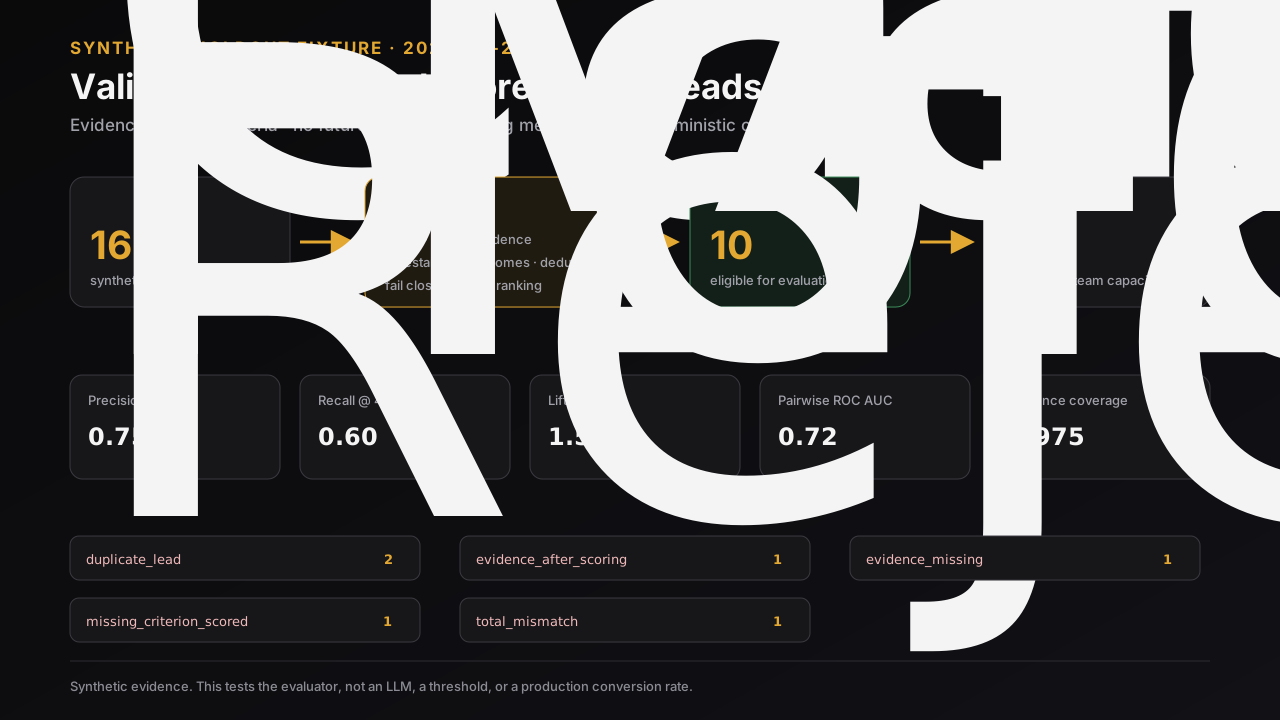
A plausible explanation does not make a score trustworthy. This fixture rejects unsupported criteria, future data, bad totals, scored missing values, and duplicate records before it ranks anything. The surviving records enter a queue sized by review capacity rather than an invented universal threshold.
Files
Evidence or zero
Each observed criterion cites a supplied signal. A missing criterion gets zero points instead of a convenient midpoint.
No future leakage
Evidence must predate scoring, and the outcome must follow it. Otherwise the record cannot enter holdout metrics.
Capacity, not folklore
The example selects the top four because that is the declared review limit. It does not present 75 or any other cutoff as universal.
Verified scope
Twenty-five tests cover score ranges, component totals, evidence ownership, timestamps, leakage, missing criteria, duplicate candidates, stable ordering, holdout metrics, saved JSON, generated SVG, and license files. In the reviewed fixture, ten of sixteen candidates entered evaluation and four entered the capacity-limited queue.